Code: github.com/PSRahul/PriorDepth · Project presentation
As part of the Advanced Topics in 3D Computer Vision practical, this project aimed to build a model that estimates the depth of objects as well as the movement of the camera from a video sequence. The model combines two state-of-the-art deep learning models:
- KeyPointNet, from Neural Outlier Rejection for Self-Supervised Keypoint Learning, for estimating the most descriptive keypoints in an image.
- DepthNet, from MonoDepth2 — Digging Into Self-Supervised Monocular Depth Estimation, for monocular depth estimation. Using only an RGB image, the network is trained to output the relative depth of the objects in the image.
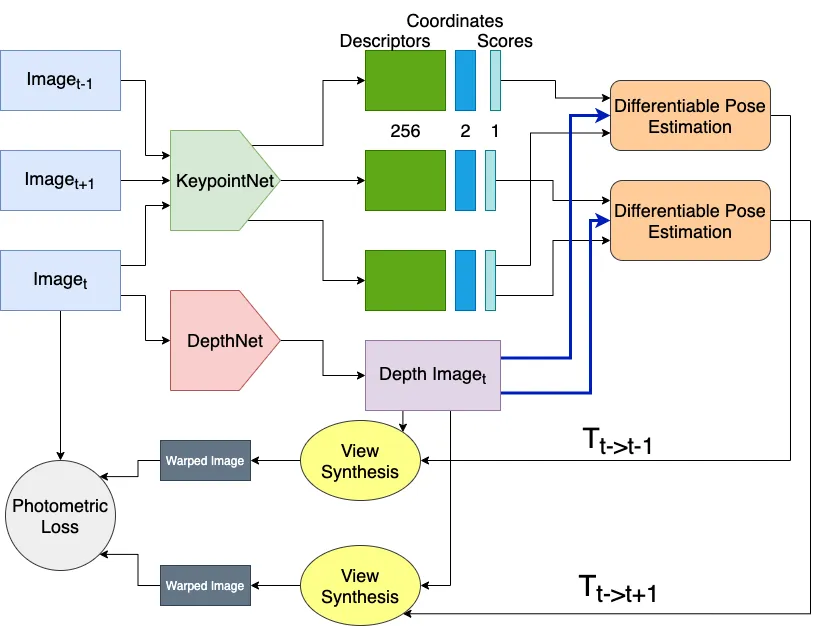
The network was designed to be trained end-to-end on autonomous driving datasets such as the KITTI Vision Benchmark Suite. The architecture is shown below.
The DepthNet was fine-tuned on a separate sequence using transfer learning so the model, originally trained on KITTI, could adapt to it. The images below show the input video sequence and the depth predicted by the model.
The keypoints from the trained KeyPointNet are further filtered by descriptor distance and matching score for more robust matching. The figures below show the keypoint matches before and after applying the distance-based filters.